

Codex Memories: What to Store and When to Reset

What you’ll learn
- The difference between recall aids that fit Codex Memories and rules that belong in the repository
- Criteria for avoiding, reviewing, or resetting a memory
- How to separate per-thread memory controls from repository rules such as AGENTS.md
Keep Codex Memories Separate from the Source of Truth
Codex Memories are best suited to recurring preferences and cautions, not mandatory team rules or sensitive information. They can reduce repeated explanation, but using memory as the source of truth makes ownership and freshness harder to verify. I separate Memories, repository rules, and temporary conversation context by who needs the information and who is responsible for updating it.
By the end of this article, you will have practical criteria for answering “What belongs in Memories, what belongs in the source of truth, and when should memory be reviewed?” in your own context.
What Codex Memories Are Good For
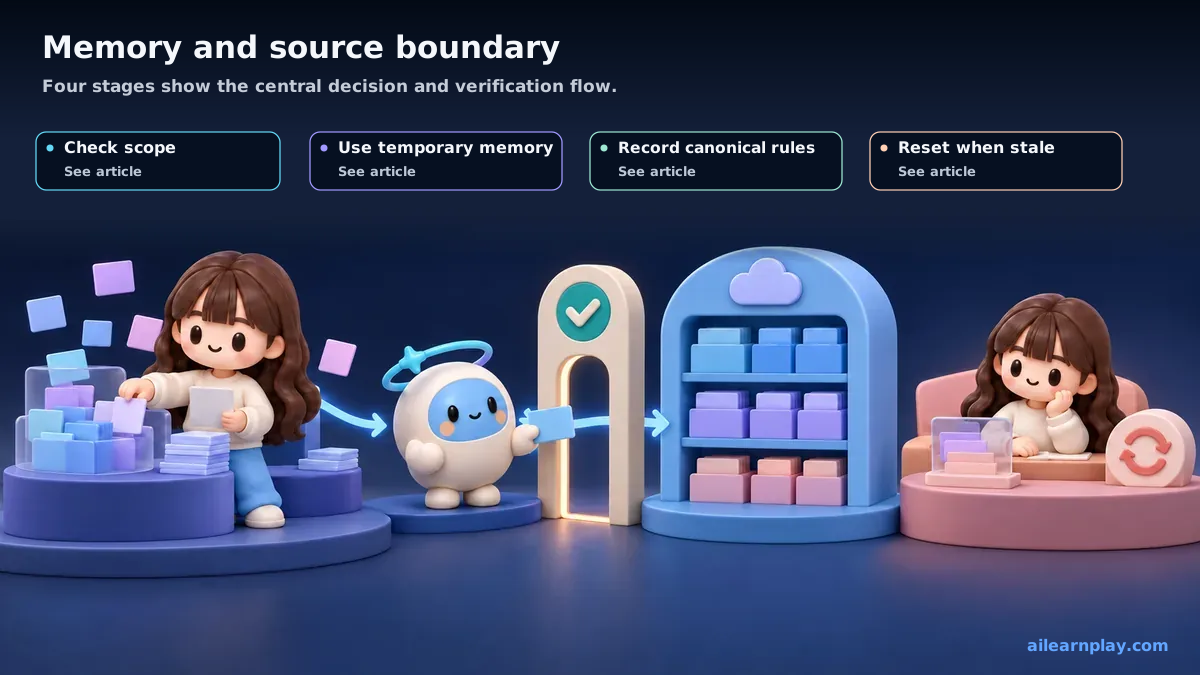
Memories are useful for information that is stable and expensive to repeat.
| Type of information | Why it fits Memories | Better source of truth |
|---|---|---|
| Personal writing preferences | They recur often but are not product specifications | Blog rules when they become mandatory |
| Frequently used verification commands | They make the initial checks easier to locate | AGENTS.md or shared workflows |
| Repository-specific cautions | They make repeated mistakes less likely | Shared rules when they become durable |
| Background behind prior decisions | They help choose the next investigation path | Versioned docs for design decisions |
This table is my operational classification. OpenAI does not publish this exact table. What the official documentation does say is that Codex can carry context such as stable preferences, recurring workflows, tech stacks, and known issues into future work.[1]
What Should Not Live in Memory
The information that should not live only in Memories is information that is harmful when missing, dangerous when stale, or required consistently across a team.
First, mandatory rules should not live only in Memories. Rules such as “run the production build only after explicit approval” or “do not publish fabricated sources” belong in AGENTS.md, shared rules, and validation scripts.
Second, secrets and customer data should not be treated as safe memory material. OpenAI’s documentation says Codex redacts secrets from generated memory fields, but it still tells users to review memory files before sharing a Codex home directory or generated memory artifacts (an output file or deliverable generated by a build or creation process).[1] I would not treat redaction as permission to enter sensitive material.
Short-lived research notes are also a poor fit. A one-off hypothesis, an unverified investigation path, or a temporary workaround can become harmful if it appears again as a remembered assumption in a later session.
Reset Codex Memories After Goal Changes, Incorrect Recall, or Irrelevant Accumulation
In this article, “reset” does not necessarily mean manually deleting memory files. It includes turning memory use or generation off for a thread, changing configuration, and inspecting generated memory state to remove outdated assumptions.
| Situation | Recommended response |
|---|---|
| Codex repeats an outdated assumption | Suspect memory, then move the correct rule into AGENTS.md or shared rules |
| The project structure changed significantly | Review memories that mention old directories, commands, or workflows |
| A thread used a lot of temporary research or external information | Do not use that thread as future memory input |
| The work involved sensitive context | Disable memory generation and inspect ~/.codex/memories/ before sharing |
| A preference became a team rule | Promote it from Memories into versioned rules or validation |
| Codex suggestions diverge from current specifications | Prefer official docs and current repository state over memory |
The most important reset signal is “convenient but wrong.” If Codex gets started faster but starts from an outdated premise, it is only making the wrong work faster. Resetting memory is less about wiping Codex clean and more about restoring the freshness of its assumptions.
Enable or Disable Codex Memories Per Thread
In the Codex app and Codex TUI, /memories controls memory behavior for the current thread. You can decide whether the thread uses existing memories and whether the thread can be used to generate future memories. Those thread-level choices do not change global memory settings.[1]
I would use thread-level control for work like this:
- Handling customer data, unpublished information, or authentication-adjacent context
- Pulling in a lot of temporary information through web search, MCP, or external tools
- Trying many incorrect hypotheses during an investigation
- Running a one-off experiment whose conclusions should not affect future sessions
The documented memory settings include memories.generate_memories, memories.use_memories, memories.disable_on_external_context, and memories.min_rate_limit_remaining_percent.[1][2] If a thread uses external context and should not become a memory source, memories.disable_on_external_context is worth checking.
Do Not Manually Edit Generated Codex Memories as a Source of Truth
Codex stores memories under the Codex home directory. By default, that is ~/.codex, and the main memory files live under ~/.codex/memories/.[1]
The official documentation says to treat these files as generated state. You can inspect them for troubleshooting or before sharing your Codex home directory, but manual editing should not be the primary control surface.[1] I prefer this order:
- For a one-off thread, control whether the thread uses or generates memories
- For a permanent rule, move it into
AGENTS.mdor shared rules - For a specification change, update versioned repository documentation and validation
- If an incorrect memory still remains, inspect and clean generated memory state
Memories are more stable when treated as a recall layer, not as a hidden settings file.
Separate Repository Rules From Memories
For Codex workflows, versioned repository rules and Memories need different responsibilities.
AGENTS.md is the entry point I want Codex to read when it enters the repository. Shared commands, constraints, verification steps, and folder responsibilities belong there or in checked-in shared rules. Anything that needs mechanical checking should also move into review commands, CI (the automated test and validation layer, often run through tools such as GitHub Actions), or another validation layer.
Memories are for recalling personal working context. “This user usually treats Japanese as the source of truth” or “this repository usually prefers targeted review commands” can be useful memory material. Once that preference becomes mandatory, it should move into repository documentation or validation.
This separation makes resets less risky. If important assumptions also live in repository documentation and validation, the workflow does not collapse when memory behavior changes.
Summary: Choose Where Information Lives by Audience and Update Ownership
Codex Memories are useful because they reduce repeated explanation. They are not the right place for mandatory rules, sensitive information, temporary hypotheses, or stale product assumptions.
My rule of thumb is simple. Put personal preferences and recurring cautions in Memories. Put team rules in AGENTS.md and shared rules. For stale assumptions, sensitive context, or temporary external research, turn memory behavior off at the thread level, avoid memory generation, or review the generated memory state. Codex work becomes more reliable when the workflow does not depend too heavily on memory.
The first action is to classify each item you want Codex to remember as a personal preference, team rule, sensitive fact, or temporary fact. Memory settings and controls can change, so check the current product behavior before disabling, reviewing, or resetting memory.
References
- OpenAI, Memories, ChatGPT Learn
- OpenAI, Configuration Reference, ChatGPT Learn
For the latest releases and updates, check the official website and official documentation.