

Automatic learning_time Normalization: Design and Implementation

What you’ll learn
- Why
learning_timenormalization belongs before editorial review - The rules for calculating reading time from Japanese and English body length
- How creation-time normalization differs from the
dev:checkandprebuildsafety nets
Normalize learning_time After Both Locale Articles Are Complete
Normalizing learning_time only before a build makes mechanically generated metadata appear during editorial review. On this site, even a correct update mixed body changes with reading-time changes. Normalization now runs after both language bodies are complete, while later checks remain a safety net for subsequent drift.
By the end of this article, you will have practical criteria for answering “When should learning_time normalization run so generated metadata does not mix with editorial diffs?” in your own context.
Normalize learning_time Immediately After the Article Bodies
The previous fix changed dev:check and prebuild (a step that runs preparation, normalization, or validation before the production build) so they run node scripts/normalize-learning-time.mjs --write before --check. That prevented prebuild validation from stopping only because learning_time had not yet been normalized.
That still left the timing too late. If frontmatter (the metadata at the top of a Markdown article, such as title, description, and date) changes only after running dev:check, the review diff contains both actual content changes and mechanical reading-time adjustments. I want harness (the set of rules, procedures, and validation that guides AI work in a project) validation to act as the final safety check, so values that can be calculated mechanically should be settled earlier in the authoring workflow.
Normalize learning_time Immediately After Both Locale Drafts Are Complete
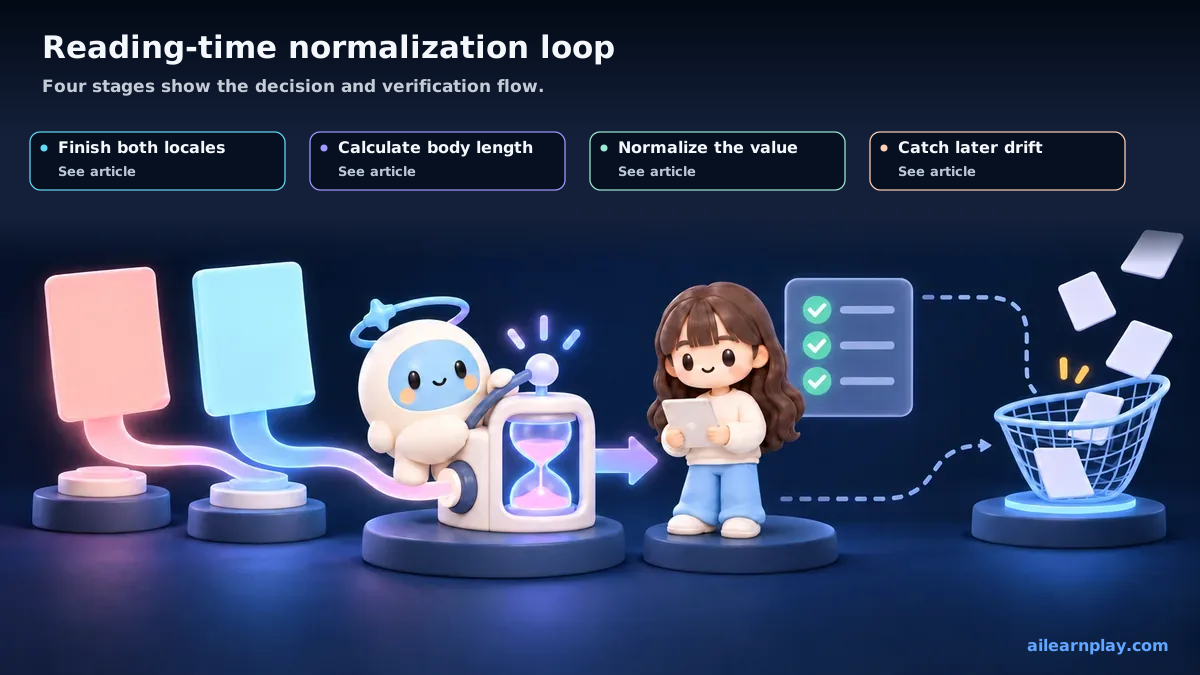
The current docs authoring and translation workflow now requires this command after the Japanese and English bodies are both in place.
npm run normalize-learning-timeThat npm script runs node scripts/normalize-learning-time.mjs --write. I added the same rule to shared/commands/docs.md, shared/skills/docs-content/SKILL.md, shared/skills/i18n-sync/SKILL.md, and shared/rules/content-i18n.md, then added a scripts/validate-harness.mjs check so the shared workflow cannot silently drop it.
The resulting sequence is: write the Japanese article, sync the English version, normalize learning_time from the actual bodies, review the content, then run dev:check as the safety net.
Calculate learning_time from Locale-Specific Body Length
scripts/normalize-learning-time.mjs reads the frontmatter and body, estimates reading time from the body, and writes the result back to learning_time. Japanese uses effective characters at about 300 characters per minute. English uses about 130 words per minute. The minimum is 5 minutes, and values are rounded to 5-minute steps.
For a short new article, a draft value such as 約8分 / About 8 minutes can become 約5分 / About 5 minutes once the script sees the actual body length. That is not a prose-quality correction. It is metadata normalization based on the article text.
For pages with hands-on time, the script calculates the reading portion from the body and keeps existing practice time values such as 実践 20分 or 20 min hands-on. Only the mechanically determined reading portion is automated; hands-on time remains an editorial decision.
dev:check and prebuild Detect Drift from Later Edits
Even with authoring-time normalization, dev:check and prebuild still run the normalizer. Existing articles can be edited, translations can be expanded, and review changes can alter the body after the initial command has run.
The responsibilities are separate. npm run normalize-learning-time during authoring keeps review diffs small. The --write and --check steps in dev:check and prebuild catch omissions and later edits. scripts/validate-harness.mjs checks that the workflow and command order do not drift in future changes.
I chose this layered design so harness validation does not become a repeated reading-time cleanup step. The value is calculated during authoring, and final validation only catches what was missed. That lets review focus on structure, evidence, and content quality.
Summary: Normalize After the Bodies Are Complete and Keep Later Checks as a Safety Net
Because learning_time is determined from body length, it is more stable to normalize it during docs authoring than to treat it as a fixed manual value. At the same time, the body can still change later, so dev:check and prebuild keep the same normalization as a safety net.
This update makes npm run normalize-learning-time part of the docs creation and translation workflow, and the harness now checks that the rule remains present. That reduces cases where draft values such as 約8分 / About 8 minutes survive until review or prebuild, and lets mechanically determined metadata settle earlier.
Start by running normalization after both language bodies are final, then review that diff separately from the prose. A site that determines reading time from criteria other than body length cannot use this calculation unchanged.